2026
CHORUS
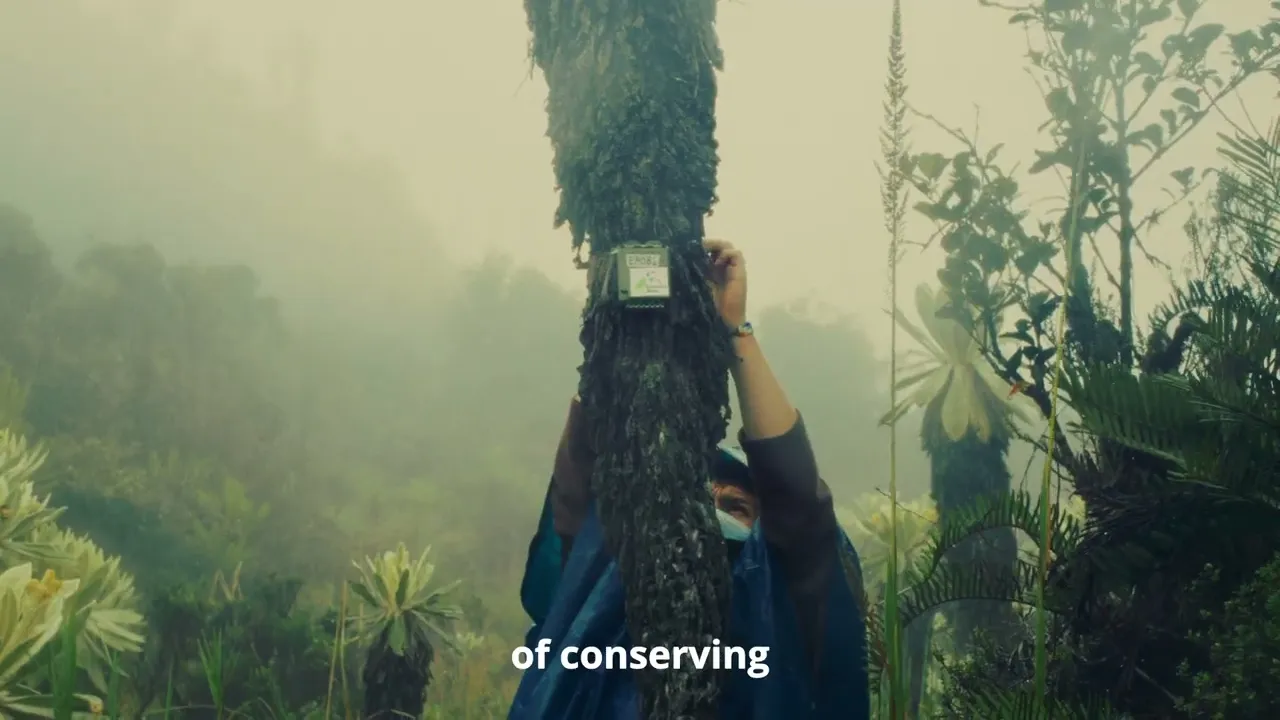
CHORUS is a 0→1 platform for discovering and monitoring wildlife through audio recordings, assisted by AI. Designed for both biodiversity scientists and non-expert community members.
TL:DR
Problem
Protected areas across Latin America are protected on paper but not monitored in practice — leaving reserves with no way to know if they’re actually meeting their conservation goals.
Without the tools or expertise to monitor their own land, reserves depend on scarce outside experts for a slow, bottlenecked process, making it difficult to guide management decisions or make the case for conservation financing.
Challenge
WildMon (a non-profit organization that builds technology to make biodiversity monitoring accessible) was hired to build a platform to scale community monitoring across Colombia, Peru, and Bolivia.
But WildMon's own biodiversity experts needed it too. Their existing pipeline was only partly built, with an interface for some stages and none for others.
Solution
A 0→1 platform that lets both biodiversity scientists and community collaborators with no AI experience run the whole monitoring workflow themselves. From importing site coordinates and audio, to seeing validated results on a dashboard.
Impact
CHORUS is now active across 8 reserves in Colombia, and will be expanded to 7 more reserves across Peru and Bolivia. The project plans to expand the use of the platform across 70+ reserves in South America.
Role
Solo Product Designer @ WildMon
Timeline
7 months
Platform
Web application
Partners
Audubon, Bezos Earth Fund
Solution overview
Import Site Coordinates
Import coordinates from every site where a recorder was placed, either manually or batch import via CSV. Sites are then shown alongside a map, allowing users to quickly spot incorrect coordinates outside the project's area bounds.
Upload Audio
Previously, users were forced to mail SD cards biodiversity scientists to run their analysis, or use an error prone upload process using an FTP server. Now, anyone can upload recordings from the field recorders and easily associate audio files with a recording site.
Search for species using AI models
Build a list of species the AI should search for by your preferred method, and run an AI search to find species in your audio recordings.
What is bioacoustics monitoring?
Bioacoustic monitoring identifies which species live in an ecosystem by analyzing the sounds they make, rather than relying on sightings. It matters because most wildlife is hard to observe directly, while sound offers a way to track biodiversity continuously and at scale.

1
Record
Audio recorders are deployed in reserves around the world, capturing sound continuously for weeks or months.
2
Analyze
The recordings are processed by species-recognition AI models trained to identify calls in the audio.

3
Output
The result is a record of which species were detected, and when and where - data that can then be visualized, reported, or acted on however a given project needs.
User Journey: Running a bioacoustics monitoring project
I conducted 5 qualitative interviews with scientists and project managers from WildMon, as well as with our partner Audubon to map out the current processes and pain points when running a monitoring project.

The Roadmap
This project focused on designing, building and shipping the MVP.
The MVP consisted of a pipeline that enables users to create a project on the platform with desired user permissions, import coordinates from the field, upload audio from the recorders, generate a potential species list, run AI analysis on the audio recordings, and validate the results of the AI analysis using their chosen validation strategy.

Feature 1
Importing site coordinates
Each time a recorder is deployed at a site, the site's coordinates are logged. These coordinates tie a recording to a specific location, and they shape three things downstream:
Which species the AI considers plausible when it searches the recordings
Where a detection appears when results are shown on a map
Where a recorder should be placed again, if a second round of the study is meant to track change over time
Since coordinates are captured in the field, they have to be imported into the platform.
Where this feature sits in the pipeline:

The Problem
Importing sites is where the biggest data-quality risk enters the platform. Field data collection was out of scope, so we had no control over how coordinates were captured. If bad data entered the pipeline, it would derail the quality of the downstream data.
The Approach
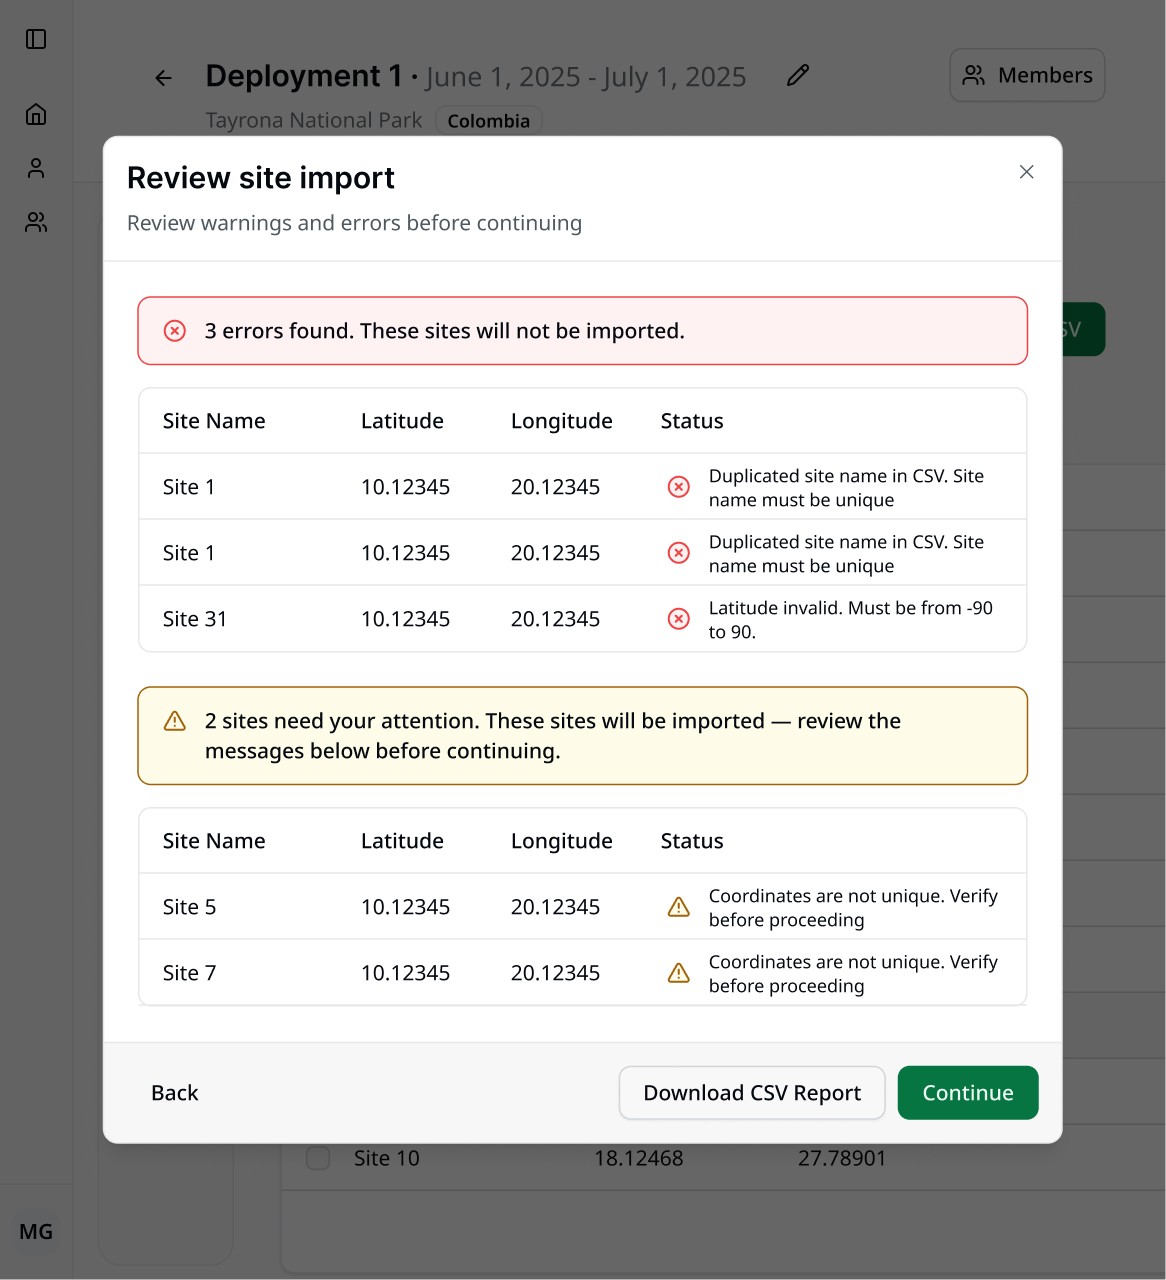
Many field teams use apps to log their site coordinates which have the ability to export a CSV. We decided to build the coordinates importer around this CSV capability, while introducing guardrails to prevent problematic coordinates from entering the platform at all.
1st Iteration
An interactive review & confirm modal let users spot warnings and fix errors on the spot.
Duplicate coordinates and existing site names surfaced as warnings; invalid coordinates were blocked outright.
Constraint
Functionality tested well with users, but engineering feasibility ruled out inline editing for the MVP.

2nd Iteration
We compromised to reduce functionality for the MVP
Users would be alerted to warnings and errors, but had to make corrections in a CSV and re-upload it, rather than fixing them on the spot.
Usability testing
Usability testing surfaced two issues:
01 Everyone downloaded the report right after seeing errors, before ever reaching the warnings screen.
02 It wasn't clear "download report" meant a CSV. Some assumed they'd have to reopen their original file and hunt for the problems themselves.

Where we landed
Errors and warnings are introduced on the same screen, and the CTA clarifies that report is a CSV download.
Feature 2
Building a species list
For the AI to detect species in a recording, someone first has to tell it what to listen for.
A single reserve can hold hundreds of species, and many sound alike, so the AI needs a list of the ones that could plausibly be there. The list narrows its search and lets the platform filter out detections that don't belong, which cuts false positives.
A list of potential species could be generated in 3 ways:
01 Region of interest
An occurrence database could pull up species that have been detected in a certain radius around each site
02 Search
Manually search and add species to the list.
03 CSV Import
Import an existing species list.
Where this feature sits in the pipeline:

Initial design
Automated list generation by region of interest.
With the goal of simplifying the process and automating wherever possible, the team leaned toward a flow that generated a potential species list automatically from the user's site coordinates. This meant first asking which animal group the user wanted to detect (birds-only pointed to eBird as the recommended taxonomy, while multi-taxa projects used GBIF) then generating the potential list without further input.
The risk
While this would serve most non-experts - it added unnecessary friction for expert users
Anyone who wanted to manually select species, or already had a CSV list, first had to delete the generated list before adding their own. And for those using the automated list, there was no visibility into how it had actually been built.
Where we landed
Asking the user for their preference upfront
I pushed to bring back a question that would generate the list - reframed around how someone wants to build their list, not which taxonomy to use.
The outcome:
A single question that served both user groups, since different projects called for different list-generation preferences
Visibility into how the region-of-interest method actually built a list, closing the transparency gap experts had run into earlier.
Feature 3 (redesign)
Validation Strategies
For every species, a human has to manually validate all the clips detected by the AI to ensure they are true presence of the species. Validation was the most manual-effort step in the pipeline — up to three weeks of full-time review on large projects.

The current state
This was a section in the pipeline that already had an interface, but it had some problems. These three problems surfaced through my own evaluation of the existing validation page.
Validation strategies (filters) were hidden under a “sort” label
Filters were used constantly, but they were ephemeral with no permanence.

The current progress tracker was useless
The tracker measured against every detection, but validators were never validating all detections. Strategy filters did not reflect the results in the tracker.

Non-experts had no way to know which validation strategy actually fit their goal.
The current state only served expert users. Choosing a strategy meant already understanding what each one was optimized for.
User Needs
WildMon's own biodiversity scientists were the ones most familiar with the current interface. I conducted informal qualitative interviews with three scientists to understand their process and pain points in depth.
01
Non-expert validators needed to focus their effort on the detections that actually mattered.
02
Project coordinators needed a way to track progress to manage time and resources.
03
Validators needed to work toward two strategies at once — one validating for model training while another validated for species inventory, on the same project.
The strategy
Validators weren't reviewing random clips — they followed a specific strategy based on their project goals.
Depending on the goal, a validator might only need the top n detections of each species per site or per day; someone training a model would instead need n detections across each confidence band. These were already goal-driven choices, just expressed as temporary filters rather than something persistent.
We turned ephemeral filters into a named, persistent validation strategy.
"Best per site" became a strategy instead of a filter — giving the tracker a defined scope to measure against, and giving non-experts a named, chooseable path toward the detections worth their time.

Initial design
Project admins add strategies that reflect their project goals directly to the project. Validators only have access to these strategies, keeping their validation efforts efficient.
The problem
Validators had no flexibility to explore strategies outside what an admin had added.
Too much reliance on admin configuration.
Iteration
A single modal handled both first-time setup and later swaps, with a toggle marking each strategy as a project goal.
The problem
The modal’s heading talked about configuring goals, but its CTA read “Apply strategy” — a mismatch that left it unclear whether you were changing your personal strategy or the project’s shared goal.

Final Design
Admin View
Project admins are provided with a CTA to set a project goal, replacing the blocking entry with a lightweight default state.
From the side panel, they are able to select project goals will which be seen by all project members.
Validator view
Validators can see which strategies are most important for the project, so they can focus their efforts on the validations that matter most.
Validators are not limited to these and can explore other strategies, and learn which use case warrants each one.
Impact
CHORUS is now active across 15 reserves in Colombia, Peru, and Bolivia.
Field deployments are complete, and recordings are moving through the platform.